The power of models
In Module 5 we saw that even an LLM is still a model: inputs, parameters fitted to data, outputs. In this module, we look at what happens when models move beyond academic exercises and shape real-world decisions, from insurance premiums to public policy.
Throughout this course, we've described models as services that transform inputs (x) into outputs (y) through optimized parameters. Here the focus shifts from how a model is built to how it is applied when real decisions depend on it.
Decision-making processes: when models determine your insurance premium
Consider this scenario: You're shopping for car insurance. The insurance company asks about your vehicle's make, model, and weight. Within seconds, their algorithm (a predictive model) calculates your premium. But what data are behind these decisions?
The chart above relates vehicle weight to crash deaths, and the models fitted to the data show two distinct patterns:
Teal line (own car occupants): As vehicle weight increases, deaths to the car's own occupants generally decrease. Heavier cars provide better protection to their passengers through mass, crumple zones, and structural integrity.
Orange line (other people): As vehicle weight increases, deaths to other people (pedestrians, cyclists, occupants of lighter vehicles) increase sharply. The physics is unforgiving: heavier vehicles transfer more energy during crashes.
The intersection point (purple dot) marks the weight at which the two models predict the same death rate. This is where the safety trade-off becomes visible. In principle, a single point like this could decide whether your insurance premium is $800 or $1,200 per year.
Real-world implications of this model:
Insurance pricing: Companies use models like this to assess risk. The risk you pose to others (the orange line) drives the price of liability cover: drive a heavy SUV and it might cost more. The risk to yourself (the teal line) drives the price of cover for your own injuries and your own car: drive a lightweight car and that part might cost more.
Urban policy: City planners use similar models to set speed limits, design bike lanes, and regulate vehicle access in dense areas. For pedestrians and cyclists, the orange line is the one that matters.
Manufacturer decisions: Making a car heavier moves it down the teal line and up the orange one. The extra mass that protects the occupants puts everyone else at greater risk.
Regulatory frameworks: A safety standard that looks only at the protection of a car's own occupants sees only the teal line. The orange line is the risk that heavier vehicles pass on to everyone else.
This is the power of models: a relationship fitted to crash data becomes the basis for decisions about the safety and finances of millions of people.
🧠 Association vs. causation
Understanding the difference between association and causation is essential when interpreting data. Just because two things happen at the same time doesn't mean one causes the other!
Let us look at an example:
Ice Cream Sales vs. Shark Attacks
(This example illustrates association, not causation.)
🍦🦈 This chart shows a strong relationship between monthly ice cream sales and shark attacks. When ice cream sales go up, so do shark attacks.
But does eating more ice cream cause more shark attacks? Of course not! They are both linked to a third factor: hot weather. More people buy ice cream and swim in the ocean when it is hot, which increases both ice cream sales and the chances of shark encounters.
This is a perfect example of association without causation, also known as a spurious correlation.
🔍 More examples of spurious correlations
Here are other pairs that are correlated but not causally connected:
-
School grades and shoe size: Younger kids tend to have smaller feet and lower grades because of age, not because foot size affects intelligence.
-
Number of firefighters and damage caused by a fire: Bigger fires need more firefighters, but sending more firefighters does not cause more damage.
-
Training load and injury: Athletes who train more might get injured more (training load is the input of the Banister modelM4), but does training cause injury, or are other factors involved (like recovery, technique, or underlying health)?
🧪 The takeaway
Association ≠ Causation. Before concluding that one thing causes another, we must rule out:
- Coincidence
- Confounding variables (a hidden factor influencing both)
- Reverse causation (maybe B causes A, not A causes B)
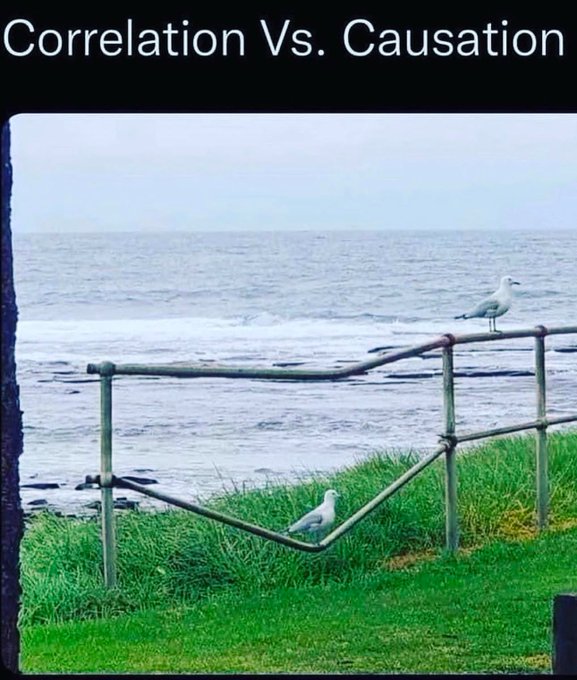
The image below encapsulates this concept quite nicely. This might well be the greatest image exemplifying the common misconception of correlation vs. causation. Credits to this X post.
That is why in science and statistics, we use experiments, controlled studies, and critical thinking to figure out what is really going on: not just what appears to be true from the data.
Looking back
One idea from this course is worth carrying out of it. In Module 4, the same first-order equation, , described VO₂ kinetics, the Banister model, a moving average and an RC circuit (One equation, many systemsM4). The models you meet in practice are often old friends in disguise: once you recognize the structure, you can borrow what other fields already know about it.
This is the last module of the course, so let me close where we started. In Module 1, the final step of the modeling processM1 was accreditation, which answers the question Can I use this model in everyday practice? Every model in this course, from the CP curve to the Banister model to a neural network, has to pass that test before it informs a decision about an athlete. And when it does, the questions in The responsibility of modelers at the start of this module become your questions too.
Wrap-up
Well done, you have completed the sixth and last module of this course.